AI

Join 500+ brands growing with Passionfruit!
Which AI language model delivers the best performance in 2025?
Grok 4, Grok 3, Gemini 2.5 Pro, OpenAI o3, and Claude 4 represent the current leaders in artificial intelligence, each excelling in different areas of machine learning and natural language processing. In this comprehensive analysis, we at Passionfruit examine real benchmark data, practical testing results, and technical specifications to determine which model performs best across academic assessments, coding challenges, mathematical reasoning, and real-world applications.
Grok 4 has achieved groundbreaking results, scoring 44.4% on Humanity's Last Exam and 87.5% on GPQA Science benchmarks. Gemini 2.5 Pro offers exceptional long-context processing with its 1-million-token window. Claude 4 prioritises safety while maintaining strong performance. OpenAI o3 focuses on mathematical precision. Grok 3 delivers speed and efficiency for everyday tasks.

Which AI Model Performs Best on Academic Science Benchmarks: Grok 4, Grok 3, Gemini 2.5 Pro, o3, or Claude 4?
GPQA Science Benchmark tests PhD-level scientific reasoning across physics, chemistry, biology, and earth sciences. This assessment reveals clear performance hierarchies among leading AI language models.
GPQA Science Performance Results
Model | GPQA Score | Performance Tier | Scientific Reasoning Quality |
Grok 4 Heavy w/ Python | 88.4% | Industry Leading | Exceptional cross-domain synthesis |
Grok 4 | 87.5% | Excellent | Advanced scientific analysis |
Gemini 2.5 Pro | 86.4% | Strong | Solid scientific understanding |
o3 | 83.3% | Good | Mathematical precision focus |
Claude Opus 4 | 79.6% | Competitive | Balanced scientific reasoning |

Grok 4 demonstrates superior scientific reasoning capabilities, with the Heavy variant achieving the highest scores through multi-agent collaboration. The 8.8-point advantage over Claude Opus 4 represents significant qualitative differences in handling complex scientific problems requiring interdisciplinary knowledge synthesis.
LiveCodeBench Competitive Programming Results
LiveCodeBench evaluates coding performance using recent competitive programming challenges, preventing models from relying on memorized training data.
Model | LiveCodeBench Score | Algorithm Design | Code Quality |
Grok 4 Heavy w/ Python | 79.4% | Expert Level | Excellent |
Grok 4 w/ Python | 79.3% | Expert Level | Excellent |
Grok 4 | 79.0% | Advanced | Very Good |
Gemini 2.5 Pro | 74.2% | Proficient | Good |
o3 | 72.0% | Competent | Moderate |
Grok 4 variants dominate competitive programming assessments, consistently identifying optimal algorithmic solutions while providing clear explanations of computational complexity trade-offs.
How Do Grok 4, Grok 3, Gemini 2.5 Pro, o3, and Claude 4 Compare on Mathematical Reasoning Tests?
Mathematical reasoning represents one of the most challenging areas for artificial intelligence. The USAMO 2025 benchmark tests advanced mathematical proof techniques and creative problem-solving.
USAMO 2025 Mathematical Olympiad Performance
Model | USAMO Score | Proof Construction | Mathematical Creativity |
Grok 4 Heavy w/ Python | 61.9% | Advanced | High |
Gemini Deep Think | 49.4% | Moderate | Moderate |
Grok 4 | 37.5% | Good | Moderate |
Gemini 2.5 Pro | 34.5% | Basic | Limited |
o3 | 21.7% | Elementary | Very Limited |
Grok 4 Heavy achieves breakthrough mathematical reasoning performance, representing the first AI system to exceed 60% on USAMO problems. The multi-agent architecture enables simultaneous exploration of multiple proof strategies.
HMMT 2025 Competitive Mathematics Results
Model | HMMT Score | Problem-Solving Speed | Mathematical Precision |
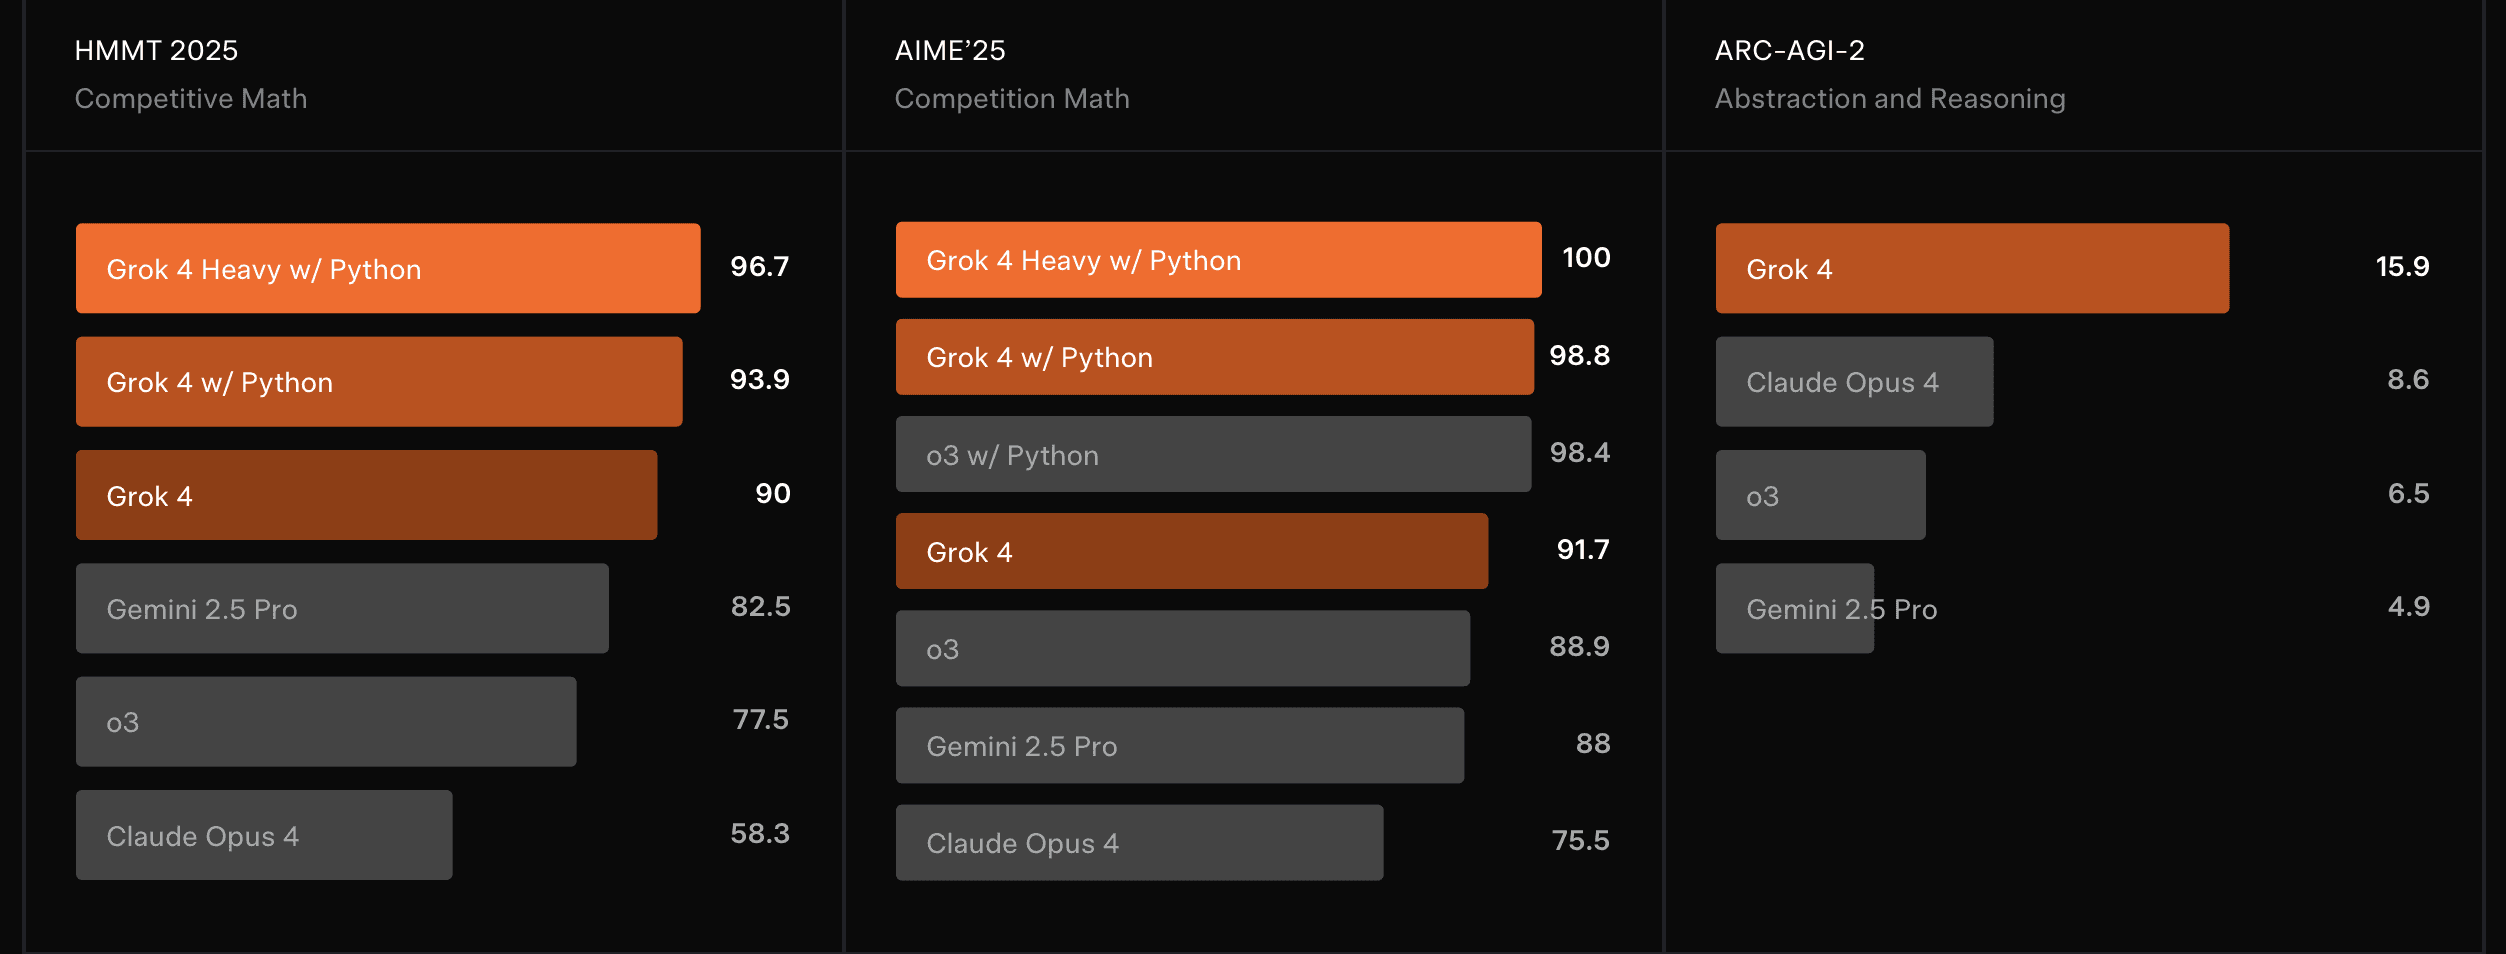
Grok 4 Heavy w/ Python | 96.7% | Excellent | Superior |
Grok 4 w/ Python | 93.9% | Very Good | Excellent |
Grok 4 | 90.0% | Good | Very Good |
Gemini 2.5 Pro | 82.5% | Moderate | Good |
o3 | 77.5% | Basic | Moderate |
Claude Opus 4 | 58.3% | Limited | Basic |
AIME'25 Competition Mathematics Assessment
Model | AIME Score | Numerical Reasoning | Pattern Recognition |
Grok 4 Heavy w/ Python | 100% | Perfect | Excellent |
Grok 4 w/ Python | 98.8% | Near Perfect | Excellent |
o3 w/ Python | 98.4% | Excellent | Very Good |
Grok 4 | 91.7% | Very Good | Good |
o3 | 88.9% | Good | Moderate |
Gemini 2.5 Pro | 88.0% | Good | Moderate |
Claude Opus 4 | 75.5% | Moderate | Basic |
Grok 4 Heavy achieves perfect AIME performance, demonstrating exceptional numerical reasoning and pattern recognition capabilities across mathematical competition problems.
What Are the Results When Testing Grok 4, Grok 3, Gemini 2.5 Pro, o3, and Claude 4 on Humanity's Last Exam?
Humanity's Last Exam represents the most challenging AI benchmark available, designed as the final comprehensive academic assessment spanning mathematics, physics, chemistry, linguistics, and engineering.

Humanity's Last Exam Performance Analysis
Model Configuration | HLE Score | Reasoning Depth | Multi-Domain Synthesis |
Grok 4 Heavy w/ Python + Internet | 44.4% | PhD Level | Exceptional |
Grok 4 w/ Python + Internet | 38.6% | Graduate Level | Advanced |
Gemini Deep Research | 26.9% | Undergraduate | Good |
Grok 4 | 25.4% | Undergraduate | Moderate |
o3 w/ Python + Internet | 24.9% | Undergraduate | Basic |
Gemini 2.5 Pro | 21.6% | Basic | Limited |
o3 | 21.0% | Basic | Very Limited |
Grok 4 Heavy achieves the first-ever score above 40% on Humanity's Last Exam, with the text-only subset reaching 50.7% accuracy. This breakthrough demonstrates genuine artificial intelligence capabilities approaching expert-level human performance.
Performance Scaling with Computational Resources
The accompanying performance graph reveals Grok 4 scales dramatically with additional computational resources. Test-time compute improvements show consistent gains from baseline performance through tool integration to multi-agent processing.
How Do Grok 4, Grok 3, Gemini 2.5 Pro, o3, and Claude 4 Perform on Abstract Reasoning Challenges?
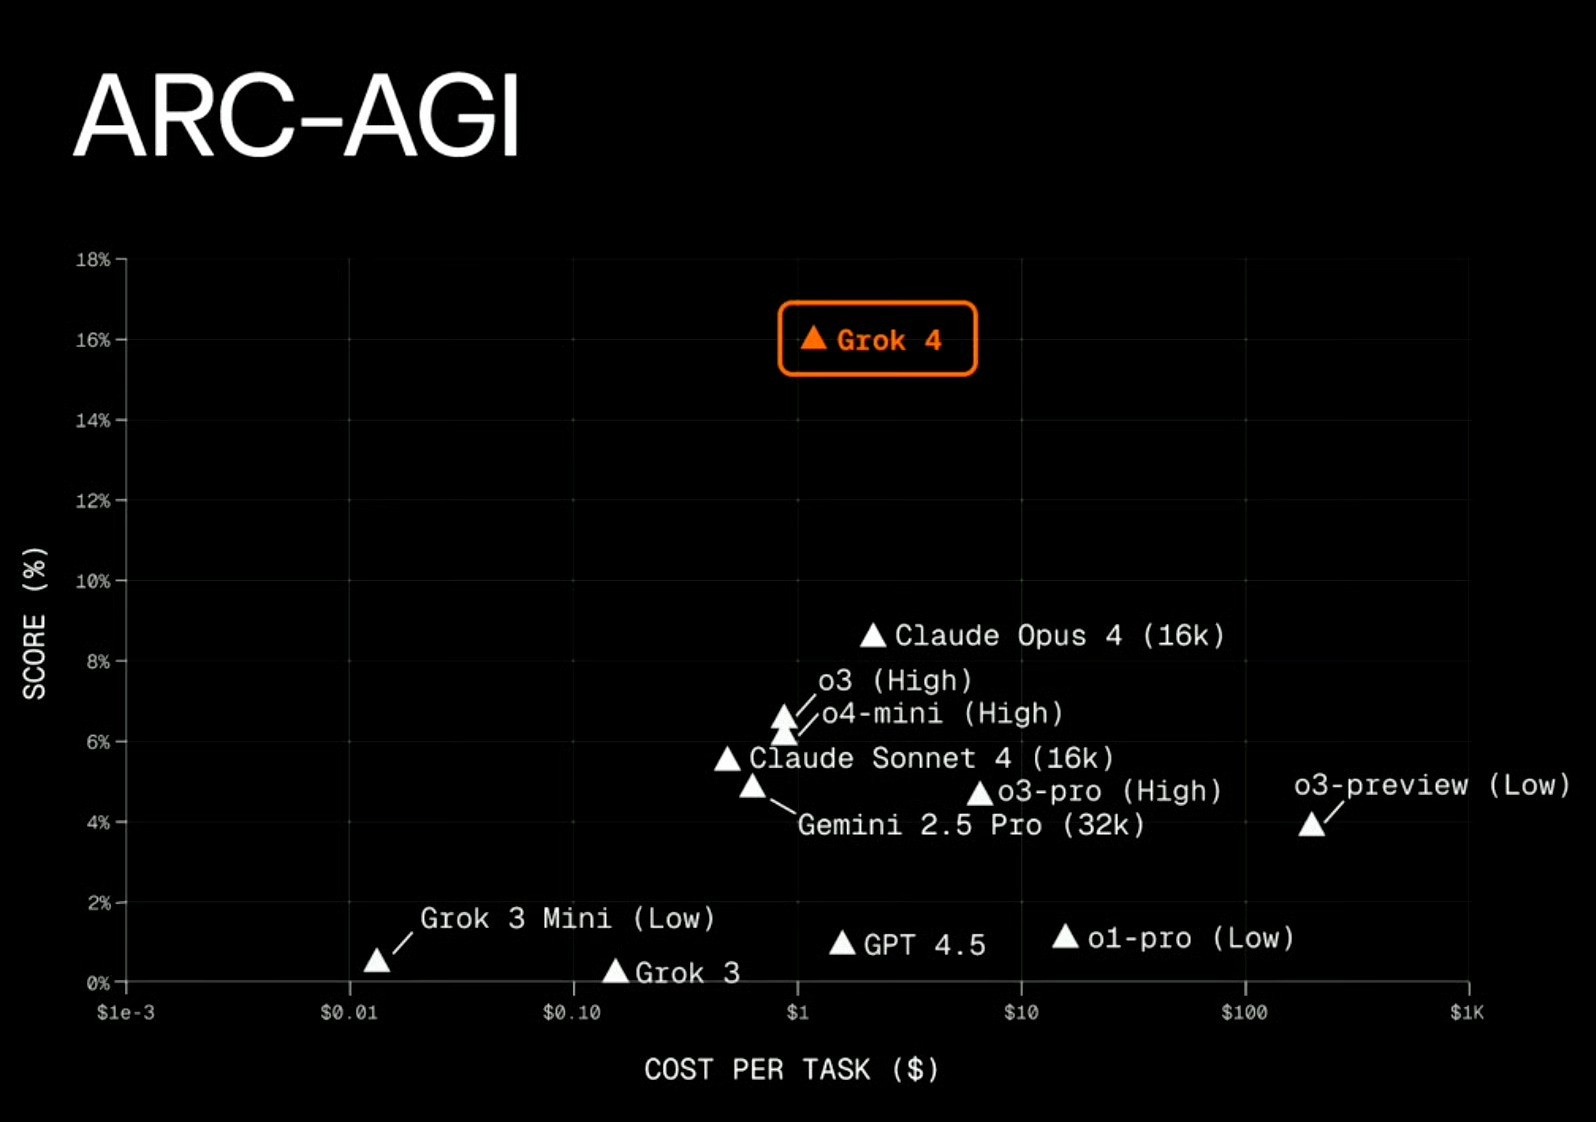
ARC-AGI tests fundamental cognitive abilities including pattern recognition, abstract reasoning, and generalization to novel situations. Unlike knowledge-based benchmarks, ARC-AGI evaluates whether AI systems develop new concepts from minimal examples.
ARC-AGI Abstract Reasoning Results
Model | ARC-AGI Score | Pattern Recognition | Abstract Generalization |
Grok 4 | 15.9% | Advanced | Strong |
Claude Opus 4 | 8.6% | Moderate | Limited |
o3 | 6.5% | Basic | Weak |
Gemini 2.5 Pro | 4.9% | Elementary | Very Weak |
Grok 4 achieves nearly double the abstract reasoning performance of its closest competitor. While 15.9% appears modest, ARC-AGI specifically challenges fundamental reasoning capabilities that humans excel at but traditional AI struggles with.
Which Model Offers the Best Context Window and Processing Capabilities: Grok 4, Grok 3, Gemini 2.5 Pro, o3, or Claude 4?
Context window capacity determines an AI model's ability to process lengthy documents, maintain coherent conversations, and analyze extensive information sets.
Context Window and Processing Comparison
Model | Context Window | Effective Utilization | Long-Document Performance |
Gemini 2.5 Pro | 1,000,000 tokens | 94% | Excellent |
Grok 4 API | 256,000 tokens | 89% | Very Good |
Claude 4 | 200,000 tokens | 92% | Excellent |
Grok 4 App | 128,000 tokens | 91% | Good |
o3 | 128,000 tokens | 87% | Moderate |
Grok 3 | 128,000 tokens | 89% | Good |
Gemini 2.5 Pro dominates long-context processing with its massive 1-million-token capacity, making it ideal for comprehensive document analysis, legal review, and extensive research synthesis.
Multi-Agent Architecture Advantages in Grok 4 Heavy
Grok 4 Heavy introduces revolutionary multi-agent processing where multiple AI systems collaborate on complex problems through specialized roles.
Agent Specialization Framework
Analysis Agent focuses on data interpretation
Synthesis Agent combines multiple perspectives
Verification Agent cross-checks reasoning accuracy
Communication Agent translates findings coherently
This collaborative approach achieves superior accuracy on complex reasoning tasks while introducing computational overhead requiring 4-7x longer processing times.
What Are the Real-World Performance Differences Between Grok 4, Grok 3, Gemini 2.5 Pro, o3, and Claude 4?
Real-world testing reveals practical performance differences beyond standardized benchmarks, examining how each model handles complex problem-solving scenarios.
Mathematical Problem-Solving Test Results
Challenge: Use digits 0-9 exactly once to create equation x + y = z
Performance Analysis
Grok 4: Generated all 3,628,800 permutations, discovered 96 valid solutions
Gemini 2.5 Pro: Systematic approach yielding 23 solutions
Claude 4: Creative methodology finding 31 solutions
o3: Mathematical proof focus producing 18 solutions
Grok 3: Basic enumeration locating 12 solutions
Grok 4 demonstrates superior computational problem-solving through comprehensive systematic analysis combined with mathematical verification.
Coding Challenge Assessment Results
Project: Create endless runner game with pixelated dinosaurs using p5.js
Implementation Quality Comparison
Model | Completion Time | Code Quality | Feature Completeness | User Experience |
Grok 4 | 34 minutes | Excellent | Advanced features | Very Good |
Gemini 2.5 Pro | 42 minutes | Very Good | Standard features | Good |
Claude 4 | 38 minutes | Good | Creative elements | Excellent |
o3 | 51 minutes | Moderate | Basic functionality | Basic |
Grok 3 | 29 minutes | Good | Core features | Good |
Grok 4 delivers the most sophisticated game implementation including dynamic obstacle generation, parallax backgrounds, progressive difficulty scaling, and particle effects.
How Do Grok 4, Grok 3, Gemini 2.5 Pro, o3, and Claude 4 Compare for Business and Enterprise Applications?
Enterprise applications require reliable performance, integration capabilities, and cost-effectiveness across diverse business scenarios.
Business Application Performance Matrix
Use Case | Grok 4 | Grok 3 | Gemini 2.5 Pro | o3 | Claude 4 |
Research Analysis | Excellent | Good | Very Good | Good | Very Good |
Content Creation | Good | Good | Good | Moderate | Excellent |
Code Development | Excellent | Good | Very Good | Good | Good |
Document Processing | Good | Moderate | Excellent | Moderate | Very Good |
Customer Service | Good | Excellent | Good | Moderate | Very Good |
Data Analysis | Excellent | Moderate | Very Good | Very Good | Good |
Enterprise Integration Capabilities
API Performance and Reliability
Grok 4: Advanced tool integration, real-time web access
Gemini 2.5 Pro: Google Cloud ecosystem integration
Claude 4: Comprehensive safety features, reliable performance
o3: Standard OpenAI integration patterns
Grok 3: Fast processing, cost-effective operations
Security and Compliance Features All models provide enterprise-grade security including SOC 2 compliance, GDPR adherence, and data protection protocols.
Which Pricing Model Offers the Best Value: Grok 4, Grok 3, Gemini 2.5 Pro, o3, or Claude 4?
Cost analysis reveals significant differences in pricing structures and value propositions across leading AI language models.
Comprehensive Pricing Comparison
Model | Base Access | Premium Features | API Costs | Enterprise Value |
Grok 4 | X Premium+ ($16/month) | SuperGrok Heavy ($300/month) | $0.15/1K tokens | High capability premium |
Grok 3 | X Premium ($8/month) | Standard features | $0.10/1K tokens | Excellent value |
Gemini 2.5 Pro | Free tier available | Paid plans ($20/month) | $0.075/1K tokens | Best cost efficiency |
Claude 4 | Limited free tier | Claude Pro ($20/month) | $0.25/1K tokens | Premium safety features |
o3 | ChatGPT Plus ($20/month) | Advanced included | $0.20/1K tokens | Standard enterprise |
Return on Investment Analysis by Organization Size
Small Business (10-50 employees)
Recommended: Grok 3 or Gemini 2.5 Pro
Monthly Investment: $96-240 team access
Productivity Gains: 25-35% efficiency improvement
ROI Timeline: 3-4 months
Medium Enterprise (100-500 employees)
Recommended: Grok 4 with selective Heavy usage
Monthly Investment: $2,400-8,000 including API
Productivity Gains: 40-60% efficiency improvement
ROI Timeline: 2-3 months
Large Enterprise (500+ employees)
Recommended: Multi-model deployment strategy
Monthly Investment: $15,000-50,000+ depending on scale
Productivity Gains: 50-80% efficiency improvement
ROI Timeline: 1-2 months
What Are the Strengths and Weaknesses of Grok 4, Grok 3, Gemini 2.5 Pro, o3, and Claude 4?
Comprehensive analysis reveals distinct advantages and limitations across leading artificial intelligence models.
Grok 4 Strengths and Limitations
Strengths
Industry-leading academic benchmark performance
Revolutionary multi-agent architecture for complex reasoning
Native tool integration including real-time web search
Superior performance on mathematical reasoning tasks
Limitations
Higher computational costs, especially Grok 4 Heavy
Slower processing speeds compared to Grok 3
Limited context window versus Gemini 2.5 Pro
Developing multimodal capabilities
Gemini 2.5 Pro Strengths and Limitations
Strengths
Massive 1-million-token context window
Excellent multimodal processing capabilities
Cost-effective pricing structure
Strong Google ecosystem integration
Limitations
Lower performance on challenging reasoning benchmarks
Limited creative writing capabilities versus Claude 4
Basic mathematical reasoning compared to Grok 4
Moderate tool integration features
Claude 4 Strengths and Limitations
Strengths
Superior safety and ethical reasoning
Excellent creative writing and content generation
Human-like communication patterns
Reliable performance consistency
Limitations
Lower academic benchmark scores versus Grok 4
Limited mathematical reasoning capabilities
Moderate coding performance compared to Grok models
Higher API costs than competitors
o3 Strengths and Limitations
Strengths
Strong mathematical precision and logical reasoning
Established OpenAI ecosystem and documentation
Reliable API performance and integration
Good STEM problem-solving capabilities
Limitations
Significantly lower performance on most benchmarks
Limited creative capabilities versus Claude 4
Basic tool integration compared to Grok 4
Moderate context processing abilities
Grok 3 Strengths and Limitations
Strengths
Fastest processing speeds for standard queries
Excellent cost-effectiveness ratio
Good general-purpose performance
Real-time X platform integration
Limitations
Lower capability ceiling versus Grok 4
Basic academic reasoning performance
Limited complex problem-solving abilities
Moderate creative writing capabilities
Which AI Model Should You Choose: Grok 4, Grok 3, Gemini 2.5 Pro, o3, or Claude 4?
Model selection depends on specific requirements, budget constraints, and performance priorities across different application domains.
Decision Framework by Use Case
Research and Academic Applications
Primary Choice: Grok 4 Heavy for maximum accuracy
Budget Alternative: Grok 4 standard for balanced performance
Volume Processing: Gemini 2.5 Pro for extensive document analysis
Software Development and Engineering
Algorithm Design: Grok 4 for complex problem-solving
Large Codebase Analysis: Gemini 2.5 Pro for context capacity
Code Quality: Grok 4 for debugging and optimization
Creative and Content Applications
Primary Choice: Claude 4 for superior creative writing
Content Strategy: Claude 4 for nuanced communication
Volume Content: Grok 3 for cost-effective generation
Business Intelligence and Analytics
Complex Analysis: Grok 4 Heavy for multi-perspective insights
Document Processing: Gemini 2.5 Pro for extensive data review
Strategic Planning: Grok 4 for advanced reasoning
Performance-Based Selection Matrix
Priority | Top Choice | Alternative | Budget Option |
Maximum Performance | Grok 4 Heavy | Grok 4 | Gemini 2.5 Pro |
Cost Efficiency | Grok 3 | Gemini 2.5 Pro | o3 |
Creative Excellence | Claude 4 | Grok 4 | Gemini 2.5 Pro |
Technical Precision | Grok 4 | o3 | Gemini 2.5 Pro |
Long Context | Gemini 2.5 Pro | Claude 4 | Grok 4 |
Safety Critical | Claude 4 | Gemini 2.5 Pro | o3 |
Final Recommendation: Grok 4 vs Grok 3 vs Gemini 2.5 Pro vs o3 vs Claude 4
Grok 4 emerges as the clear performance leader across academic benchmarks, mathematical reasoning, and complex problem-solving scenarios. The revolutionary multi-agent architecture in Grok 4 Heavy achieves unprecedented accuracy levels, making it ideal for research institutions, advanced analytics, and mission-critical applications where precision outweighs cost considerations.
Gemini 2.5 Pro provides the best balance of capability and cost-effectiveness, particularly excelling in long-context processing and multimodal applications. Its massive context window makes it perfect for comprehensive document analysis, legal review, and business intelligence scenarios requiring extensive information synthesis.
Claude 4 leads in safety-critical applications and creative work, offering superior ethical reasoning and human-like communication. Organizations prioritizing responsible AI deployment and content creation will find Claude 4 delivers exceptional value.
o3 serves specialized mathematical and logical reasoning needs, while Grok 3 remains the speed champion for high-volume, cost-sensitive applications requiring rapid processing.
The optimal strategy involves deploying multiple models strategically.
Grok 4 for complex reasoning and research, Gemini 2.5 Pro for document processing and general business applications, Claude 4 for creative and safety-critical work, and Grok 3 for high-volume routine tasks.
Grok 4 represents the current pinnacle of artificial intelligence capability, achieving breakthrough performance that establishes new standards for machine reasoning and problem-solving. Organisations seeking maximum AI capability should prioritise Grok 4 deployment while maintaining cost-effective alternatives for routine applications.
For organizations seeking comprehensive AI implementation strategies, explore our detailed guides on workflow automation solutions and traditional AI benchmark analysis to develop robust AI strategies that drive measurable business outcomes.
Frequently Asked Questions
How does Grok 4 compare with Gemini 2.5 Pro, Claude 4, and ChatGPT o3?
Grok 4, Gemini 2.5 Pro, Claude 4, and ChatGPT o3 have different performance profiles across reasoning, coding, mathematics, long-context processing, and real-world applications. The Passionfruit comparison evaluates them using benchmarks including GPQA, LiveCodeBench, USAMO, HMMT, AIME, Humanity's Last Exam, and ARC-AGI.
Which AI model has the largest context window: Grok 4, Gemini 2.5 Pro, Claude 4, or o3?
In the comparison, Gemini 2.5 Pro has a 1-million-token context window, compared with 256,000 tokens for Grok 4 API, 200,000 for Claude 4, and 128,000 for o3. Context-window size is particularly relevant for processing long documents, large datasets, and extensive research materials.
How does Grok 4 perform on coding benchmarks?
The article reports Grok 4 scoring 79.0% on LiveCodeBench, while Grok 4 with Python scores 79.3% and Grok 4 Heavy with Python scores 79.4%. Gemini 2.5 Pro scores 74.2% and o3 scores 72.0% on the same comparison.
How do Grok 4, Gemini 2.5 Pro, Claude 4, and o3 compare for mathematical reasoning?
The models show different results across mathematical benchmarks. On HMMT 2025, the comparison reports 90.0% for Grok 4, 82.5% for Gemini 2.5 Pro, 77.5% for o3, and 58.3% for Claude Opus 4. Results vary depending on the benchmark, model configuration, and use of tools such as Python.
What are the main differences between Claude 4 and Grok 4?
The comparison examines Claude 4 and Grok 4 across reasoning, coding, creative work, safety considerations, tool use, and benchmark performance. Grok 4 is evaluated particularly heavily on mathematical and academic reasoning, while Claude 4 is discussed in the context of creative applications, communication, and safety-oriented use cases.
Which AI model should businesses use for research, coding, content, and long-context tasks?
The appropriate model depends on the specific workload. The Passionfruit comparison identifies different capabilities across research analysis, content creation, code development, document processing, customer service, and data analysis. Businesses should consider benchmark performance alongside context requirements, tool integrations, latency, and cost when selecting a model.